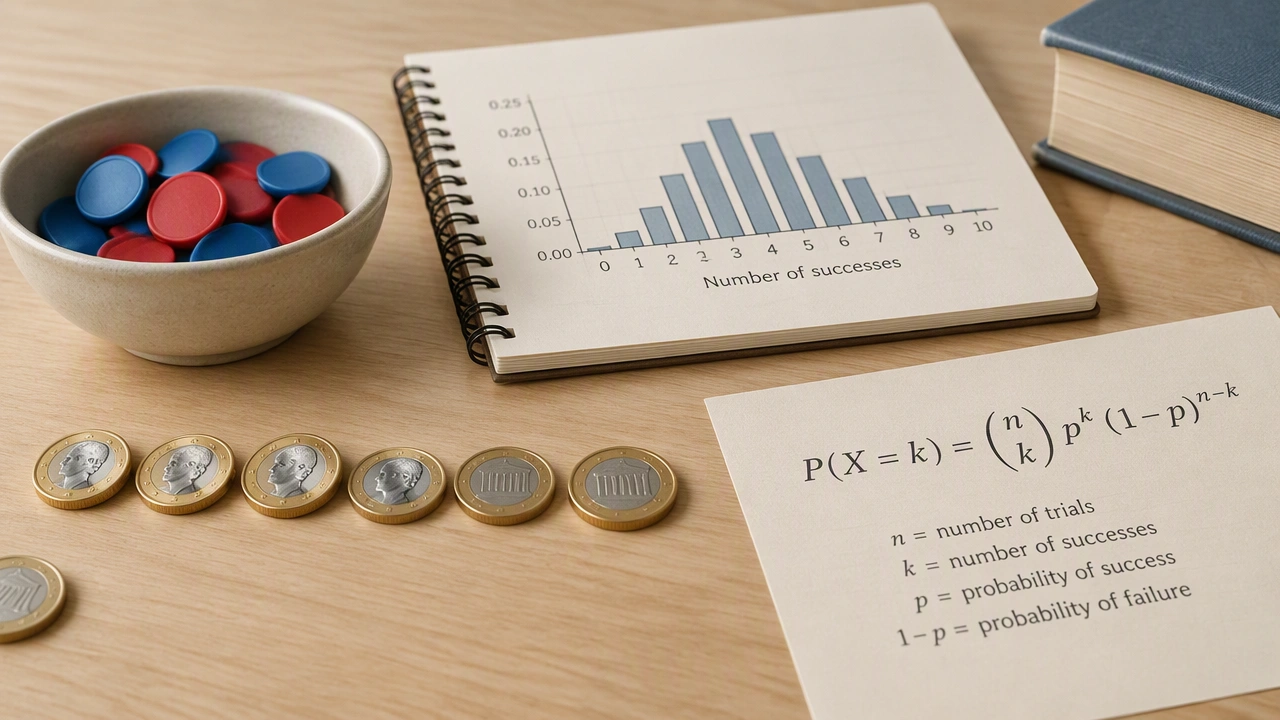
Home / Probability Distributions
The Binomial Distribution Explained: Success and Failure in Repeated Trials
Probability gives us a language for describing repeated processes whose outcomes remain uncertain. The binomial distribution is one of the most useful models in that language because it describes a simple pattern: a fixed number of independent trials, each with two possible outcomes, where the chance of success stays constant. Understanding the binomial distribution helps students, researchers, and analysts reason about how often a particular outcome should appear when the same conditions are repeated.
What counts as a binomial setting
A random variable follows a binomial distribution when four conditions are met. First, there is a fixed number of trials, written as n. Second, each trial has exactly two outcomes, labeled success and failure. Third, the probability of success, written as p, is the same for every trial. Fourth, the trials are independent, so the result of one trial does not change the probability of another.
The word success is only a label. It refers to the outcome being counted, not to something morally good. In a quality check, success might mean detecting a defect. In a classroom quiz, success might mean answering a question correctly. What matters is that the definition stays consistent throughout the analysis.
The binomial random variable X counts the number of successes in n trials. Its possible values are 0, 1, 2, …, n. For example, if a manufacturer inspects 20 light bulbs and records whether each bulb meets a brightness standard, the number of bulbs that pass can be modeled as binomial when the bulbs are inspected independently and each has the same probability of passing.
The binomial formula, step by step
The probability of observing exactly k successes in n trials is
P(X = k) = C(n, k) × pk × (1 − p)n−k
This expression has three parts, and each part answers a different question. The binomial coefficient C(n, k), sometimes written as “n choose k,” counts the number of ways to place k successes among n positions. The term pk is the probability of obtaining exactly k successes, while (1 − p)n−k is the probability of obtaining the remaining n − k failures. Multiplying these parts gives the probability of one specific count of successes after accounting for all possible arrangements.
As a concrete example, consider five independent trials with success probability p = 0.4. The probability of exactly two successes is
C(5, 2) × 0.42 × 0.63 = 10 × 0.16 × 0.216 = 0.3456.
The coefficient 10 matters because there are ten different sequences that contain two successes and three failures. Each sequence has the same probability, so the total probability is ten times the probability of one sequence.
Why the probabilities add to one
The possible values of X are mutually exclusive and cover every outcome. Summing P(X = k) for k = 0, 1, …, n therefore gives 1. This total-probability property is useful when checking calculations: if a set of binomial probabilities does not sum to approximately 1, either a term is missing or a rounding error has accumulated.
Mean, variance, and shape
The expected number of successes is E(X) = np. If a test contains 12 questions and the probability of answering each correctly is 0.75, the expected number of correct answers is 12 × 0.75 = 9. The variance is Var(X) = np(1 − p), so the standard deviation is the square root of that value. These formulas describe the center and spread of the distribution without requiring a full table of probabilities.
The value of p strongly influences the shape. When p is close to 0.5, the distribution is relatively symmetric. When p is much smaller or larger than 0.5, the distribution becomes skewed, with most probability concentrated near one end of the range. The number of trials also matters: larger n usually produces a smoother pattern, while small n can create a coarse distribution with only a few likely values.
A worked example
Suppose a quality-control process checks 8 independent components, and each component has a 0.9 probability of functioning correctly. Let X be the number that function correctly. Then X ~ Binomial(8, 0.9). The expected count is 8 × 0.9 = 7.2, and the variance is 8 × 0.9 × 0.1 = 0.72.
To find the probability that exactly 7 components function correctly, compute
C(8, 7) × 0.97 × 0.11 = 8 × 0.4782969 × 0.1 ≈ 0.3826.
To find the probability that at least 7 function correctly, add the probabilities for 7 and 8 successes. This “at least” pattern is common in reliability calculations: instead of listing every favorable case separately, identify the relevant values of k and sum their probabilities.
Assumptions, limits, and practical checks
The binomial model is only as good as its assumptions. If trials are not independent, the model may be inappropriate. If the success probability changes from trial to trial, the result is not binomial; it may be modeled by a Poisson binomial distribution instead. When sampling without replacement from a small population, the hypergeometric distribution may be more accurate because each selection changes the remaining composition.
It is also important not to confuse a theoretical probability with an observed proportion. The binomial distribution describes random variation around a fixed probability. In real data, the value of p is often unknown and must be estimated, which introduces additional uncertainty.
Connections to other ideas
The binomial distribution connects to several important topics in probability. As n grows, the normal approximation becomes useful when p is not extremely close to 0 or 1. A common rule of thumb is to check that np and n(1 − p) are both at least about 5, although exact binomial calculations remain preferable when available. The Poisson approximation can be helpful when n is large and p is very small, with np remaining moderate.
The binomial model also provides a foundation for statistical inference. Confidence intervals for a proportion and hypothesis tests about a proportion often begin with the assumption that the count of successes is binomial. Understanding the formula therefore supports both probability calculations and later statistical reasoning.
Key takeaways
- Fixed trials: The model requires a predetermined number of independent trials.
- Two outcomes: Each trial is classified as success or failure under a consistent definition.
- Constant probability: The same p applies to every trial.
- Counting successes: The random variable records how many successes occur, not their order.
- Formula logic: The binomial coefficient counts arrangements, while the powers assign probabilities.
With these ideas in place, the binomial distribution becomes less like a memorized formula and more like a structured way to reason about repeated uncertainty. It shows how small, simple rules for individual trials combine into predictable patterns across many trials.